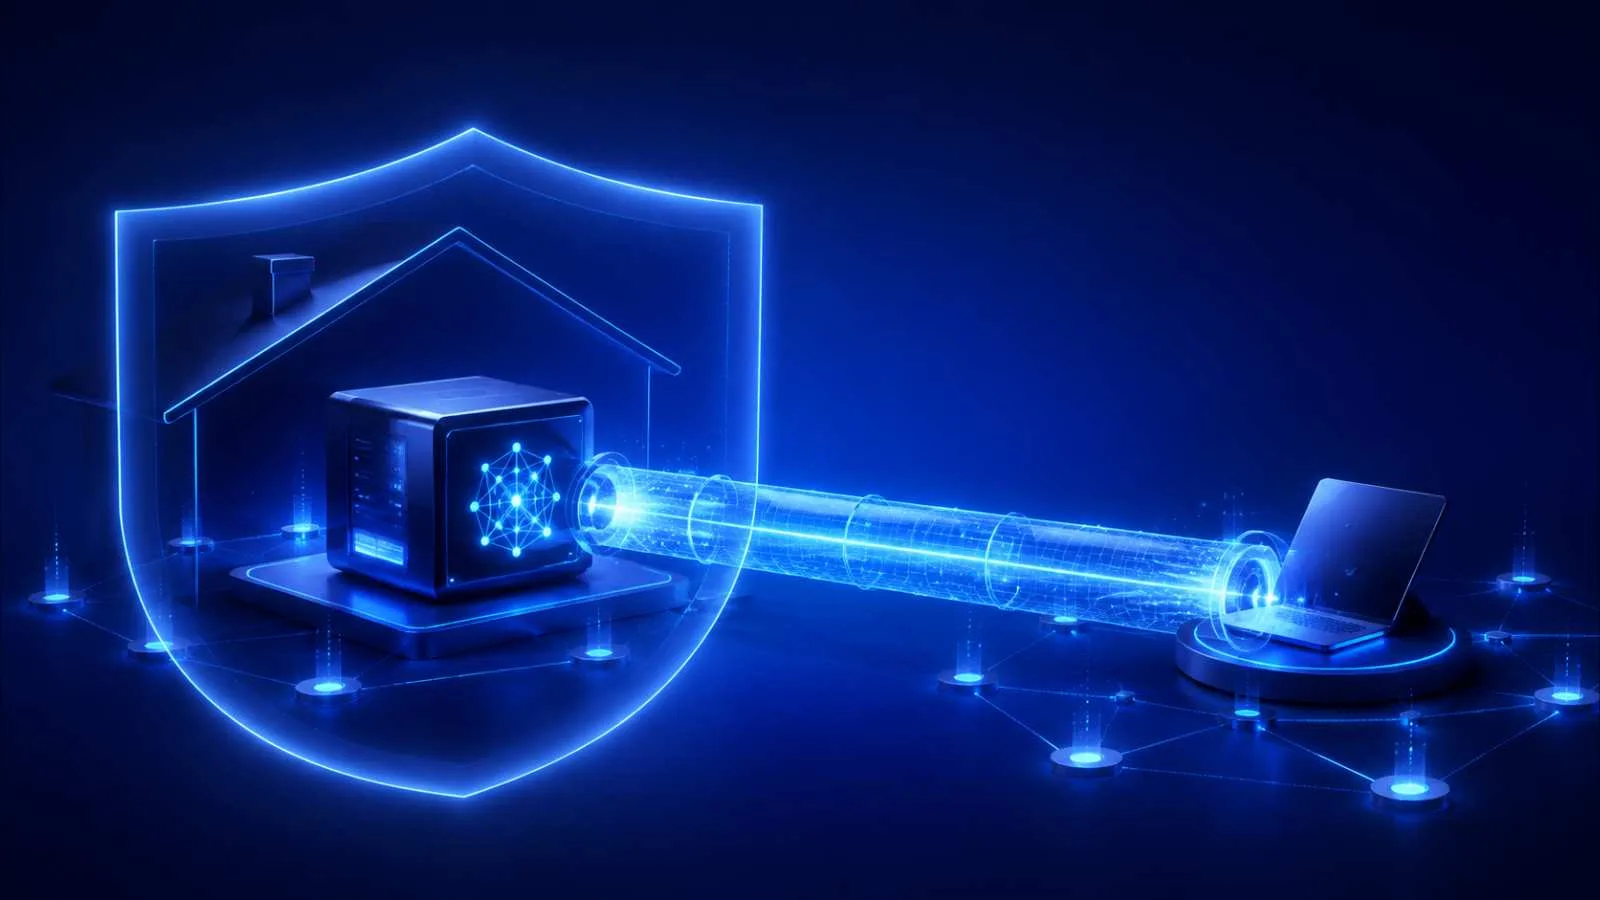
Running a local Large Language Model (LLM) such as Llama 3, Mistral, or Gemma on your own desktop or server offers substantial advantages in terms of privacy, cost control, and customizability. However, a practical challenge quickly arises when you're not physically behind that powerful computer. How do you access your local LLM from a laptop on the go, a tablet, or a remote workplace, without opening your network to unauthorized parties?
Directly opening ports via port forwarding on your router is extremely risky. Automated scanners discover open ports within minutes, which can lead to intrusion or abuse of your system through unsecured API endpoints. An elegant, robust, and secure solution to this problem is using Tailscale. In this article, we go step by step through how you can make your local LLM infrastructure accessible anywhere in the world via an encrypted mesh network (Tailnet).
Why Tailscale for Remote Network Access?
Tailscale is a zero-configuration VPN service built on the modern, efficient WireGuard protocol. Unlike traditional VPNs, where all network traffic is routed through a central VPN server, Tailscale builds a direct peer-to-peer mesh network between your devices.
The main advantages of Tailscale for exposing a local LLM are:
- No open ports (No Port Forwarding): Your router doesn't need to be modified. No inbound ports are opened on the firewall.
- End-to-end encryption: Traffic between your mobile device and your LLM server is encrypted directly between the devices with WireGuard.
- Fixed IP addresses (MagicDNS): Each device gets a fixed IPv4/IPv6 address within your private network and a simple domain name via MagicDNS (for example
http://gpu-server:11434). - Simple identity management: Access is authenticated via existing identity providers such as Google, Microsoft, or GitHub, including support for two-factor authentication (2FA).
Architecture of a Secure Local LLM Setup
Before we start the installation, it's useful to review an overview of how the components work together. A typical architecture consists of three layers: the LLM backend, the optional web interface, and the Tailscale network.
| Component | Example Software | Default Port | Function |
|---|---|---|---|
| LLM Host / Inference Server | Ollama, LM Studio, vLLM | 11434 (Ollama)1234 (LM Studio) |
Runs the AI model on the GPU/CPU and processes inference requests via a REST API. |
| Web User Interface (Optional) | Open WebUI, AnythingLLM | 3000 or 8080 |
Provides a graphical chat interface in the browser for the end user. |
| Secure Network Layer | Tailscale Daemon | N/A (WireGuard UDP) | Provides an isolated, encrypted connection between client and host. |
Step 1: Installing Tailscale on the Host Machine and Client
To get started, Tailscale needs to be installed both on the computer running the LLM (the host) and the devices from which you want to gain access (the clients, such as a laptop or phone).
1. Creating an Account and Installing
Sign up at tailscale.com and create a free account. Then download and install the Tailscale client on the host machine (suitable for Linux, Windows, and macOS).
For Linux servers, use the official installation script:
curl -fsSL https://tailscale.com/install.sh | sh
sudo tailscale up
Follow the link in the terminal to add the device to your personal Tailnet. Repeat the installation on your laptop or mobile phone and sign in with the same account.
Step 2: Configuring the LLM Service for Network Access
By default, most local LLM engines listen only on the local loopback interface (127.0.0.1 or localhost). To accept requests via the Tailscale network, the server must be configured to listen on all network interfaces (0.0.0.0) or specifically on the Tailscale IP address.
Option A: Configuring Ollama
If you use Ollama, set the environment variable OLLAMA_HOST to 0.0.0.0.
On Linux (systemd): Edit the systemd service configuration with the command:
sudo systemctl edit ollama.serviceAdd the following lines to the opened file:
[Service]
Environment="OLLAMA_HOST=0.0.0.0"
Save the file and restart the Ollama service:
sudo systemctl daemon-reload
sudo systemctl restart ollama
On Windows / macOS: Set the environment variable OLLAMA_HOST=0.0.0.0 within your system settings, or start Ollama via the terminal:
OLLAMA_HOST=0.0.0.0 ollama serveImportant Security Warning: By having the service listen on 0.0.0.0 , it accepts connections from every network interface on the host. Make sure your local OS firewall (such as ufw on Ubuntu or Windows Defender Firewall) blocks direct incoming connections on the LLM port from the local physical network, while still allowing traffic via the tailscale0 network interface.
Option B: Configuring LM Studio
In LM Studio, go to the tab Local Server (the developer icon). Here, check the option "Serve on Local Network" and set the bind address setting to 0.0.0.0. Then click Start Server. The API is now available on port 1234.
Step 3: Connecting from the Remote Device
Once Tailscale is active on both devices and your LLM server is listening on the correct interface, you can view the IP addresses of your Tailnet in the Tailscale Dashboard or via the terminal on the client:
tailscale statusHere you'll see the specific IP address of your host machine (this usually starts with 100.x.y.z). With MagicDNS, you can also use the machine name, for example gpu-server.
Testing the Connection
From your remote laptop, you can now send an HTTP request to the LLM server over the Tailscale network. For example, for Ollama:
curl http://100.x.y.z:11434/api/generate -d '{
"model": "llama3",
"prompt": "Waarom is de hemel blauw?"
}'
If the installation was successful, you'll immediately receive a streamed JSON response back from your own server at home or at the office.
Step 4: Adding a Graphical Web UI (Open WebUI)
Calling the REST API directly is convenient for developers, but for everyday use, a visual interface such as Open WebUI is more pleasant. You can run Open WebUI on the host machine via Docker:
docker run -d -p 3000:8080 \
-e OLLAMA_BASE_URL=http://127.0.0.1:11434 \
-v open-webui:/app/backend/data \
--name open-webui \
--restart always \
ghcr.io/open-webui/open-webui:main
From any device within your Tailnet, navigate in the browser to http://100.x.y.z:3000 or http://gpu-server:3000 to use your personal ChatGPT-like interface.
Advanced Security and Options: Tailscale Serve & ACLs
For users who want extra security layers or simplified URLs without port numbers, Tailscale offers two powerful built-in features:
1. Tailscale Serve for Automatic HTTPS Certificates
With Tailscale Serve , you can automatically forward traffic and provide it with a valid Let's Encrypt TLS certificate within your private network. You won't need to remember a port :11434 or :3000 number anymore:
sudo tailscale serve --bg 3000Your Open WebUI interface is now directly reachable at https://gpu-server.your-tailnet.ts.net via a fully encrypted HTTPS connection.
2. Setting Up Access Control Lists (ACLs)
If you share your Tailnet with family members or colleagues, you may not want everyone to have full access to the LLM host's settings. Via the Tailscale Admin Console, you can define ACL rules to restrict access to specific ports (such as port 11434).
// Voorbeeld ACL JSON-snippet
"acls": [
  {
    "action": "accept",
    "src": ["group:developers"],
    "dst": ["gpu-server:11434", "gpu-server:3000"]
  }
]
Common Issues and Solutions (Troubleshooting)
- Connection Refused: Check whether the LLM service is really listening on
0.0.0.0and not on127.0.0.1. Usenetstat -tulnorss -tulnon the host to verify active ports. - Slow Response Times or Timeouts: Check via
tailscale ping <ip-adres>whether the devices have established a direct connection (Direct DERP), or whether traffic is routed through a relay server. Direct connections require that UDP traffic isn't completely blocked by your ISP or router. - OS Firewall Blocking Traffic: On Linux, you can explicitly allow Tailscale traffic with UFW:
sudo ufw allow in on tailscale0.
Conclusion
Exposing a local LLM via Tailscale is the most elegant and secure way to have access to your own AI models anywhere. It eliminates the security risks of open ports and offers a seamless, encrypted experience on laptops, smartphones, and tablets. By combining Tailscale with tools such as Ollama and Open WebUI, you build a fully private, high-quality AI platform under your own control.
For more in-depth guides on optimizing your local inference setup, check out the articles on installing and configuring Ollama on macOS and the hardware requirements for local LLMs, or the broader comparison for choosing a local model on gids.llmnet.nl.